SD Infotech helps mid-sized companies adopting AI recruiting tools decide, task by task, where AI can act on its own, where it should assist a recruiter, and where a person must stay accountable. Every recommendation rests on evidence, not vendor claims.
Keyword screening rejects people who can do the job and passes people who only list the words. Adding AI on top of an unclear requisition automates the same mistakes, faster.
qualified candidates found by a keyword screen in our screening pilot. The evidence-based screen found 10.
candidates rejected by the evidence-based screen without a person looking. The keyword screen rejected 14.
separate tasks and decisions in a typical recruiting process. Most AI decisions are made at the level of "screening" or "sourcing".
Pilot figures come from a controlled test on a constructed résumé set for one role. A live-requisition pilot is how we measure it in your organization.
An AI tool can be technically impressive and still be the wrong investment for your hiring operation. Before committing more budget, expanding automation or presenting AI capabilities to enterprise buyers, establish what the technology actually does and whether the evidence supports its use.
Find AI capabilities that duplicate what you already have, target poorly defined problems, or need process fixes before more money goes in. Employers get evidence to challenge vendor claims.
See which repetitive work automation can safely take off recruiters' desks, and where a person's review has to stay.
Find where AI can screen out, rank down or filter candidates, and whether a person with the evidence checks it first.
Put recruiter time on the decisions that need judgment, with oversight and records that hold up when a decision is questioned.
For AI vendors, the same review gives your sales team documented, independent answers to enterprise buyers' due-diligence questions. A review identifies where value and risk sit; any savings depend on what you decide to do with the findings. We do not promise savings figures.
Seven layers that take a hiring need from a vague request to a decision someone can defend. Layer 3 is the heart: what counts as proof that a person can do the work.
What must this hire change, and by when?
Outcomes and capabilities, not inherited JD lines.
Separates what a candidate has shown from what they only claim.
Designs how the decision is made. It does not make it.
Who can, should and must act on each task.
Scored per use case, never one company-wide score.
Outcome evidence that earns AI more autonomy over time.
Every task is assessed against four questions. Autonomy is earned, never assumed.
Decisions that reject a candidate stay with an accountable person.
The EHDA Decision Review (pilot) is the same method and the same standard, applied to your recruiting operation or to your product. Scope is agreed in writing at kickoff.
For TA, HR transformation and HR technology leaders deciding what their AI tools should be allowed to do.
For recruiting AI vendors whose enterprise buyers ask what the product decides on its own. More for vendors
Independent findings and recommendations, not guaranteed cost savings, compliance certification, a bias audit or software implementation. Findings separate what was claimed, documented, observed and could not be verified.
After a pilot, and scoped by proposal: the full TA Automation Map diagnostic with a 90-day plan, a live-requisition screening pilot, and a readiness re-score every 6 months.
Owns hiring quality and speed, and the decision to adopt AI.
Redesigning the TA operating model and needs a defensible allocation of work.
Selecting and configuring recruiting AI and accountable for how it behaves.
Enterprise TA and procurement teams now ask, before they sign: which decisions does the product make on its own, where does a recruiter approve, and who is accountable when a candidate is rejected? An EHDA Decision Review gives your sales team a clear, third-party answer.
Fixed scope: one product version, up to two modules, up to six AI features, one configuration and one round of factual corrections.
Independent by design. Some features come back "keep this human", and that's what makes the review worth showing a buyer.
14 candidates rejected by the machine, no person involved.
0 rejected by the machine. Every rejection left to a person.
One role, 22 résumés, two screens. The keyword screen found 3 of 11 qualified candidates; the evidence screen surfaced 10, with every rejection left to a person. The evidence screen also missed: it advanced one candidate with invented metrics, which is why interviews still verify evidence.
A controlled demonstration on a constructed résumé set for one role, not a measure of results in a live hiring operation. Method and data available on request.
Ten real job descriptions run against the résumés actually submitted. Half passed a literal keyword screen and four showed strong evidence for the role. None received a reply. Keyword matching explains only part of what filters candidates out.
Founder's own applications, analysed with consent.

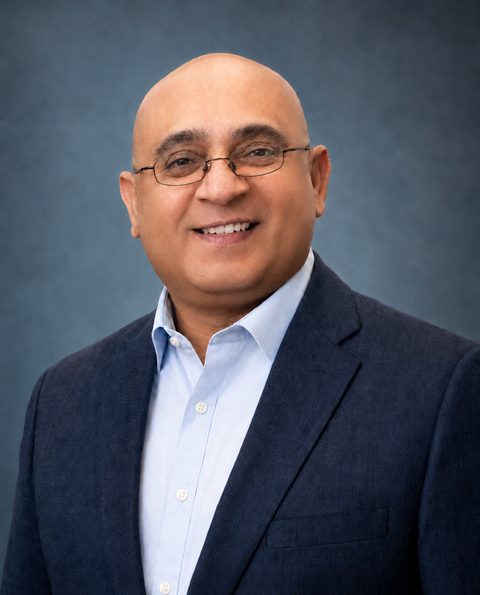
Paps Muppa founded SD Infotech LLC to fix how companies decide who gets hired, and how much of that work AI should do. He has recruited since 2001: technical and executive search, leading recruiting teams, and in-house leadership hiring at JPMorgan Chase.
EHDA came from watching good candidates rejected by filters that never read their evidence, and from watching companies adopt AI without first defining what it was allowed to decide.
Tell us whether you are an employer weighing AI tools or a vendor answering buyer questions, and which tool or task worries you. We'll tell you straight whether a two-week pilot is worth it. Not ready to talk? Get a free readiness snapshot first.